🧬 Computational Drug Discovery with Machine Learning using Python
🚀 Empowering Businesses | Transforming Data Insights 📊 | Power BI Dashboards 📈 | Data Analytics Educator 🎓 | SQL & Python 💻 | Trend Analysis 🔍
June 3, 2025
By Farhana Hoque | Data Analyst & Aspiring Data Scientist in Computational Drug Discovery.
💡 Introduction
Drug discovery is an intensive process involving the identification of bioactive compounds that can modulate disease pathways. Traditionally, this requires years of laboratory research and billions in investment. But with the advent of computational drug discovery (CDD) and machine learning (ML), we can accelerate early-stage screening to find promising drug candidates more efficiently and cost-effectively.
In this post, I’ll walk through the complete pipeline of computational drug discovery using Python, bioinformatics databases, and machine learning—demonstrating how data and algorithms are reshaping modern pharmacology.
🔬 Step-by-Step Pipeline for Virtual Screening
1️⃣ Target Selection and Bioactivity Data Retrieval
We begin by selecting a biological target (e.g., Acetylcholinesterase for Alzheimer’s treatment). Using public databases like ChEMBL, we retrieve bioactivity data (typically IC50, EC50, or Ki values) for compounds tested against this target.
📘 ChEMBL is a manually curated database of bioactive molecules with drug-like properties, used extensively in cheminformatics research.
2️⃣ Data Curation and Cleaning
The raw dataset often includes:
- Missing or null values
- Non-standard units
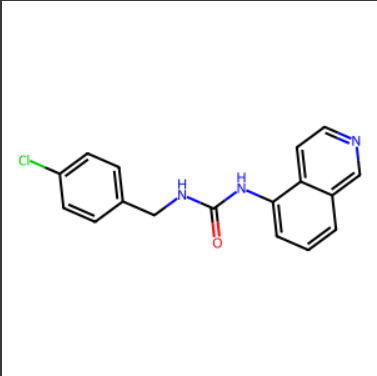
- Duplicate SMILES (chemical representations)
- Assay variations
We standardize the dataset by focusing on IC50 values and converting them to pIC50 (–log₁₀(IC50 in molar units)) for better scaling and interpretation.
3️⃣ Application of Lipinski’s Rule of Five
Before screening, we filter compounds based on drug-likeness using Lipinski’s Rule of Five, which predicts oral bioavailability. A compound is more likely to be an orally active drug in humans if it meets at least 3 of the following 4 conditions:
- No more than 5 hydrogen bond donors
- No more than 10 hydrogen bond acceptors
- Molecular weight less than 500 daltons
- LogP (octanol–water partition coefficient) less than 5
This rule helps us eliminate compounds that are unlikely to be pharmacokinetically viable.
4️⃣ Molecular Fingerprint Generation
To apply machine learning, we need numerical features. Using cheminformatics libraries (e.g., RDKit), we convert SMILES strings into molecular fingerprints like:
- Morgan fingerprints (ECFP) – circular binary vectors representing molecular substructures
- MACCS keys – predefined structural fragments
These serve as the input features (X) for our ML model.
5️⃣ Labeling the Dataset
We classify compounds into “active” and “inactive” based on their pIC50 values. A common threshold is:
- Active: pIC50 ≥ 6
- Inactive: pIC50 < 6
This binary classification approach allows us to train predictive models to distinguish between effective and ineffective compounds.
6️⃣ Machine Learning Model Training
We split the data into training and test sets and apply classification models such as:
- Random Forest
- Support Vector Machine (SVM)
- Logistic Regression
- Gradient Boosting (XGBoost)
Each model learns from patterns in the fingerprint data to predict compound activity.
7️⃣ Model Evaluation
To evaluate model performance, we use standard metrics:
- Accuracy
- Precision & Recall
- F1 Score
- ROC AUC (Area Under Curve)
A well-performing model should achieve a high AUC score and balanced precision-recall to avoid false positives or negatives in compound screening.
8️⃣ Virtual Screening of New Compounds
Once the model is trained and validated, we use it to screen new or external libraries of compounds. These may be drawn from:
- Other public datasets (e.g., PubChem, ZINC)
- In-house proprietary libraries
- Novel compounds designed via generative AI models
The output? A shortlist of potential lead candidates for lab validation.
9️⃣ Model Deployment (Optional)
To make the screening tool accessible, we can deploy the model via:
- Python GUI apps (Streamlit, Gradio)
- Web dashboards
- Command-line interfaces
- Integration with corporate data pipelines
🔁 Future Enhancements
The computational pipeline can be enhanced further by integrating:
- QSAR modeling (Quantitative Structure-Activity Relationship)
- Deep learning (e.g., Graph Neural Networks)
- ADMET profiling to assess absorption, toxicity, and metabolism
- Molecular docking simulations
🎯 Key Takeaways
✅ Public databases like ChEMBL offer high-quality bioactivity data
✅ Molecular fingerprints allow machine learning to “see” chemistry
✅ Lipinski’s Rule helps filter drug-like compounds early
✅ ML models can rapidly classify and prioritize potential leads
✅ This method reduces time and cost before lab synthesis begins
👩💻 Final Thoughts
As a data enthusiast working in the intersection of data science and life sciences, I find this area both fascinating and full of impact. The power of Python, open data, and AI can revolutionize how we discover and develop drugs — making treatments faster, cheaper, and more accessible to those in need.
If you’re passionate about #DataScience, #DrugDiscovery, or #Bioinformatics — let’s connect!
🔗 #MachineLearning #ComputationalBiology #DrugDiscovery #AIinHealthcare #Python #DataScience #RDKit #ChEMBL #LipinskiRule #Bioinformatics